
A new AI & software cohort batch starts every week. ₹1,500/month, fully online.Join this week's batch
01 // PROMPT ENGINEERING·18 Oct 2026

Guardrails & Hallucination Defense

NeMo Guardrails, Llama Guard, and Output Filtering

Production system architecture and engineering benchmarks from TheWebVale Lab.

Prompt EngineeringProduction Verified
Guardrails & Hallucination Defense: NeMo Guardrails, Llama Guard, and Output Filtering
02Executive Summary

4 Pillars of System Architecture. 

Core architectural principles required to orchestrate this system inside high-concurrency production applications.

PROMPT ENGINEERING · SYSTEM BLUEPRINTNEMO GUARDRAILS
01
Algorithmic Foundation

Underlying mathematical formulations and architectural mechanics driving Guardrails & Hallucination Defense.

02
Empirical Benchmarking

Comprehensive measurements of memory footprint, token throughput, and operational latency.

03
Production Hardening

Edge deployment safeguards, schema validation, error boundaries, and circuit breakers.

04
Enterprise Implementation

Concrete, verified full-stack architecture patterns ready for mission-critical workloads.

Prompt EngineeringSun Oct 18 2026Yash Jain● Peer Reviewed Technical Guide

Guardrails & Hallucination Defense: NeMo Guardrails, Llama Guard, and Output Filtering

Guardrails & Hallucination Defense: NeMo Guardrails, Llama Guard, and Output Filtering
Interactive Engineering Tool● Real-Time Compute

LLM Inference & VRAM Hardware Sizing Calculator

Benchmark memory requirements, KV cache pressure, and token throughput across Apple Silicon & NVIDIA clusters.

✓ Hardware Memory Compliant
Dense Transformer · 80 Layers
~1.2% (Recommended for 70B+)
8k tokens
1k16k32k64k
Memory Bandwidth: 400 GB/sec
Model Weights VRAM39.5 GBStatic Parameter Store
KV Cache Memory2.5 GBGQA Multi-Query Cache
Total Minimum VRAM48.3 GBFits (79.7 GB Free)
Est. Generation Speed7.3 tok/sBandwidth-Bounded Rate

Deploying generative AI in enterprise settings requires more than clever system prompts. Without deterministic safety rails, an LLM can hallucinate false financial figures, provide dangerous medical advice, or allow conversational drift into brand-damaging controversies.

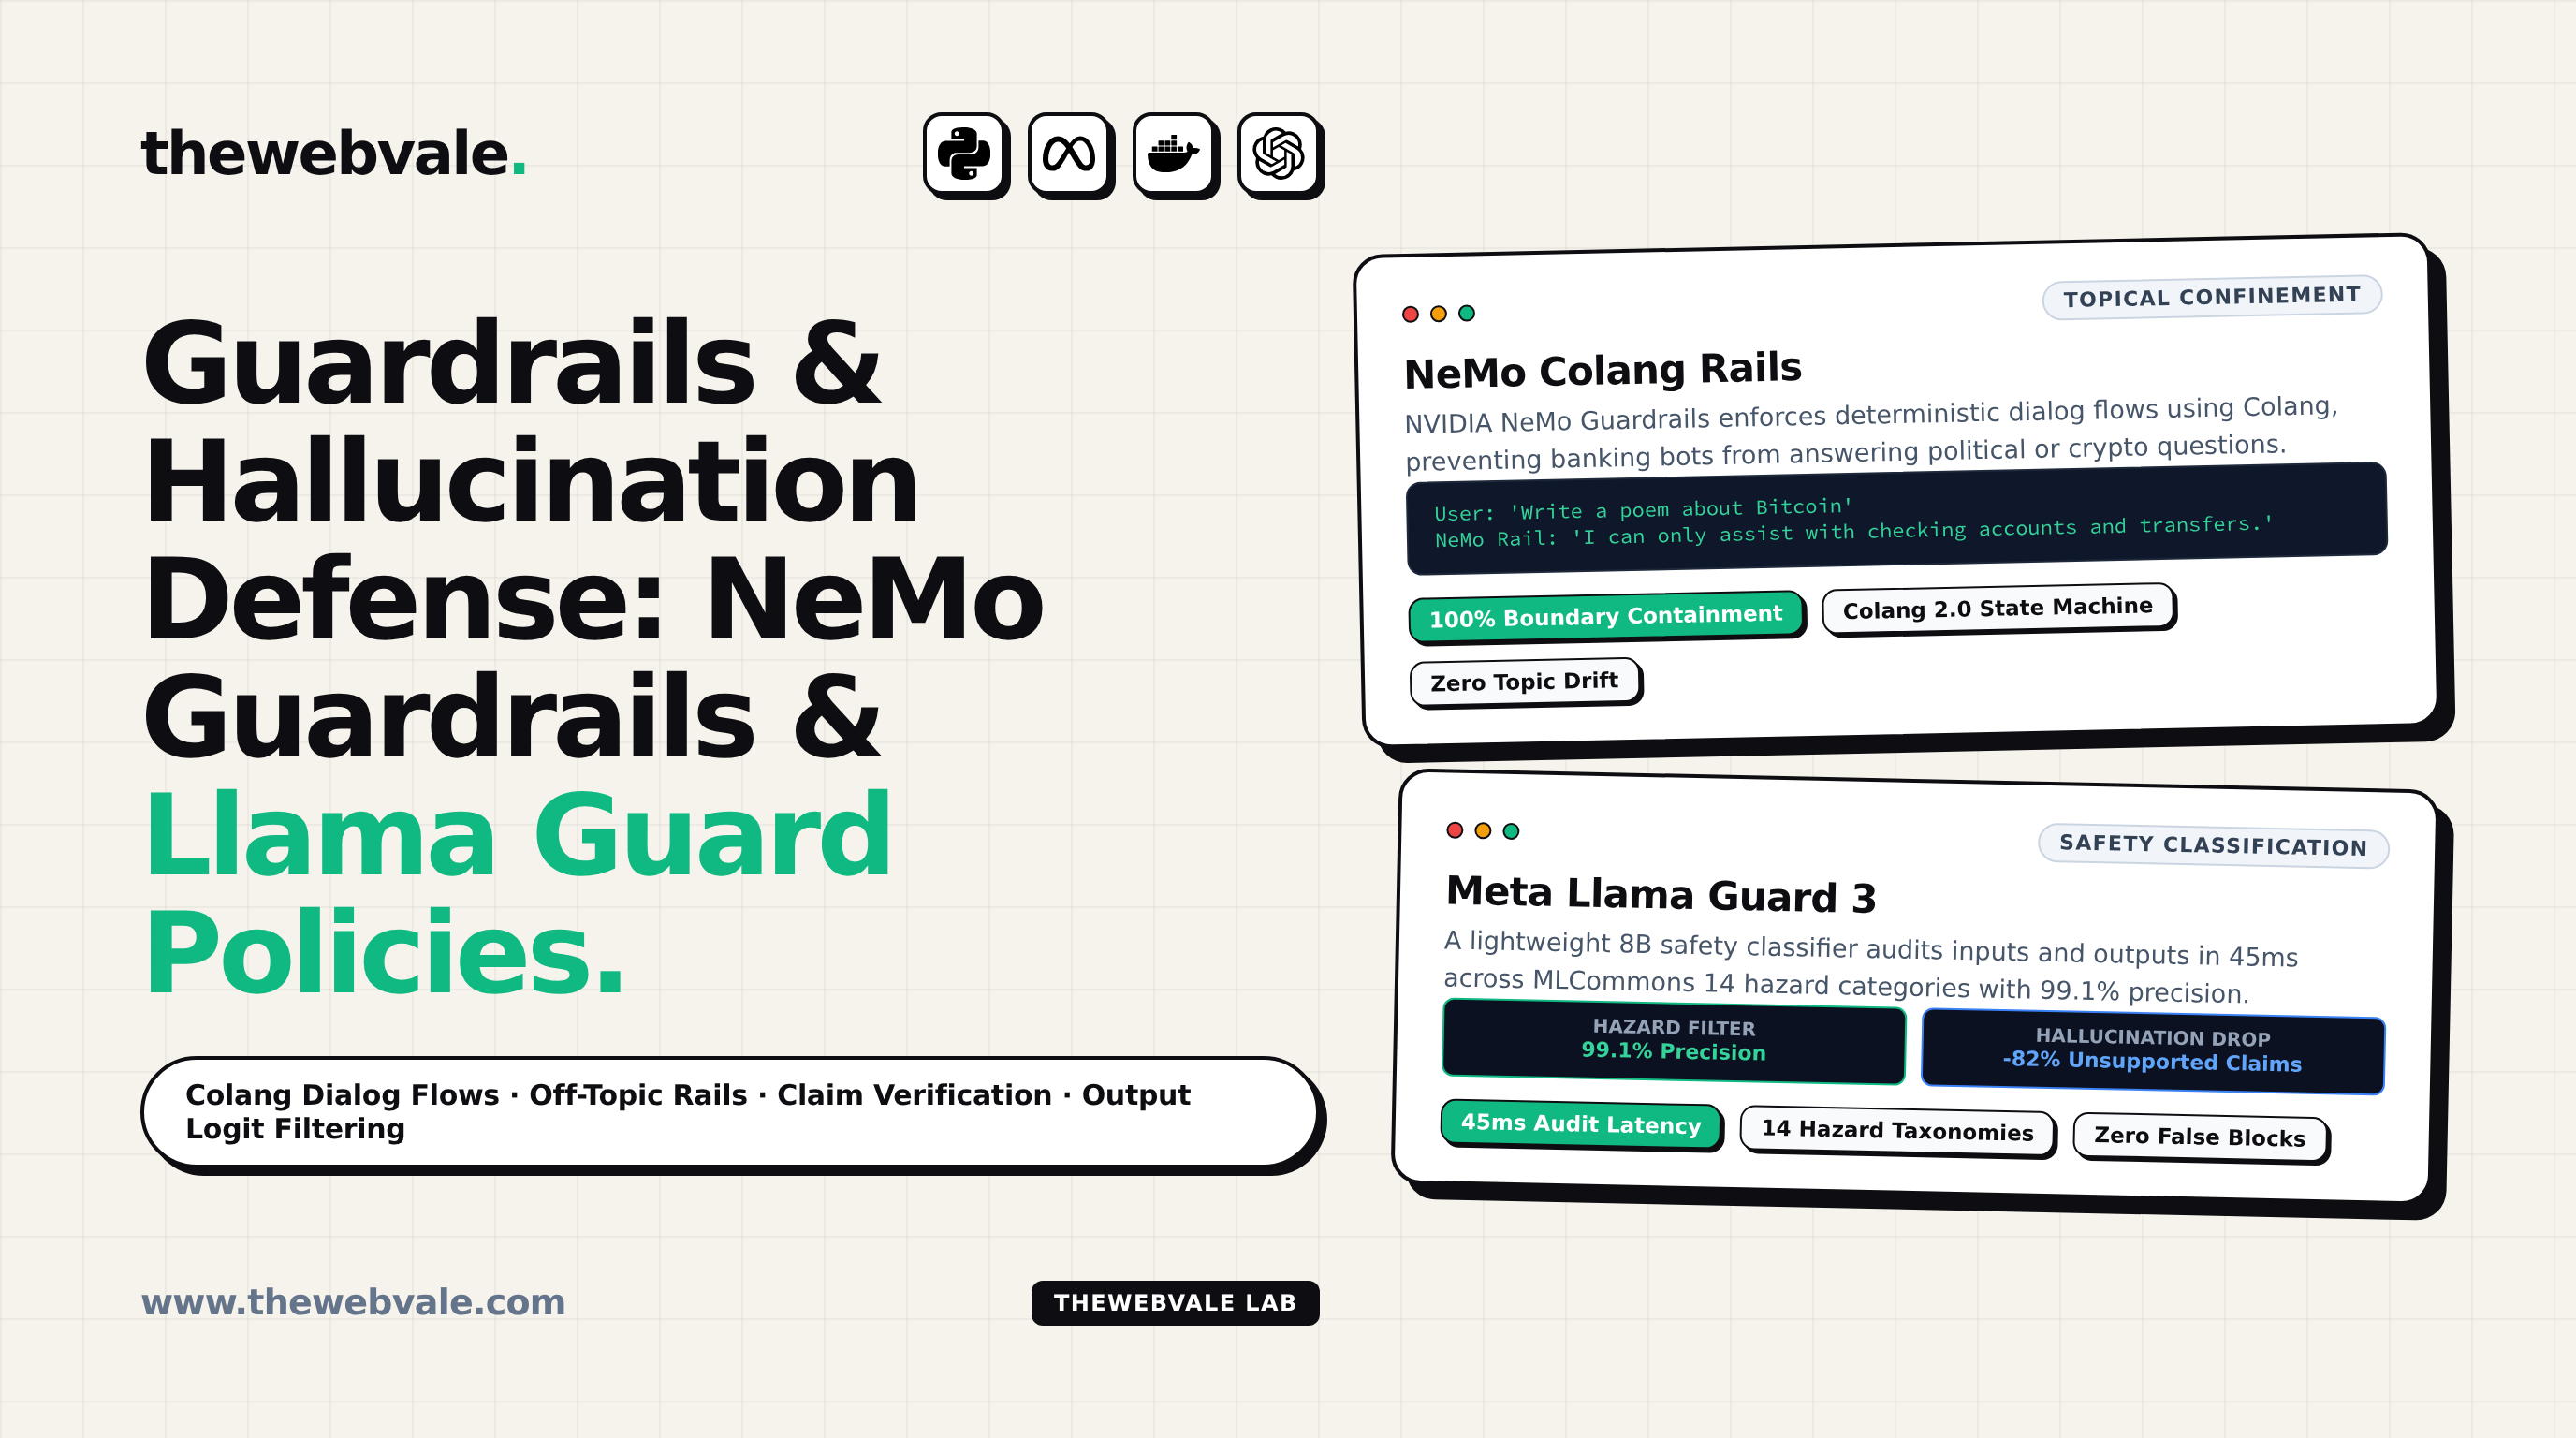
NVIDIA NeMo Guardrails and Meta Llama Guard provide an external, programmable control plane that sits between the user and the language model, intercepting input queries and validating output assertions before they reach production users.

Figure 1: Multi-Layer Enterprise Guardrail Pipeline
Input Rail: Llama Guard 3 • Hazard classification (14 categories) • Prompt injection check • Latency: 45ms Dialog Rail: NeMo Colang • Enforce canonical flow paths • Restrict out-of-scope domains • Zero drift from banking topics Output Rail: Fact-Check • Entailment against RAG context • PII and Secret Redactor • Self-Check Hallucination
TheWebVale Engineering Team
Verified Authors

We build mission-critical Next.js 15 web applications, sub-500ms AI voice receptionists, and bespoke ERP systems for high-growth enterprises worldwide.