
Prompt EngineeringSun Oct 18 2026Yash Jain● Peer Reviewed Technical Guide
Temperature, Top-P & Repetition Penalty: Dialing Hyperparameters for Code vs. Creative Tasks
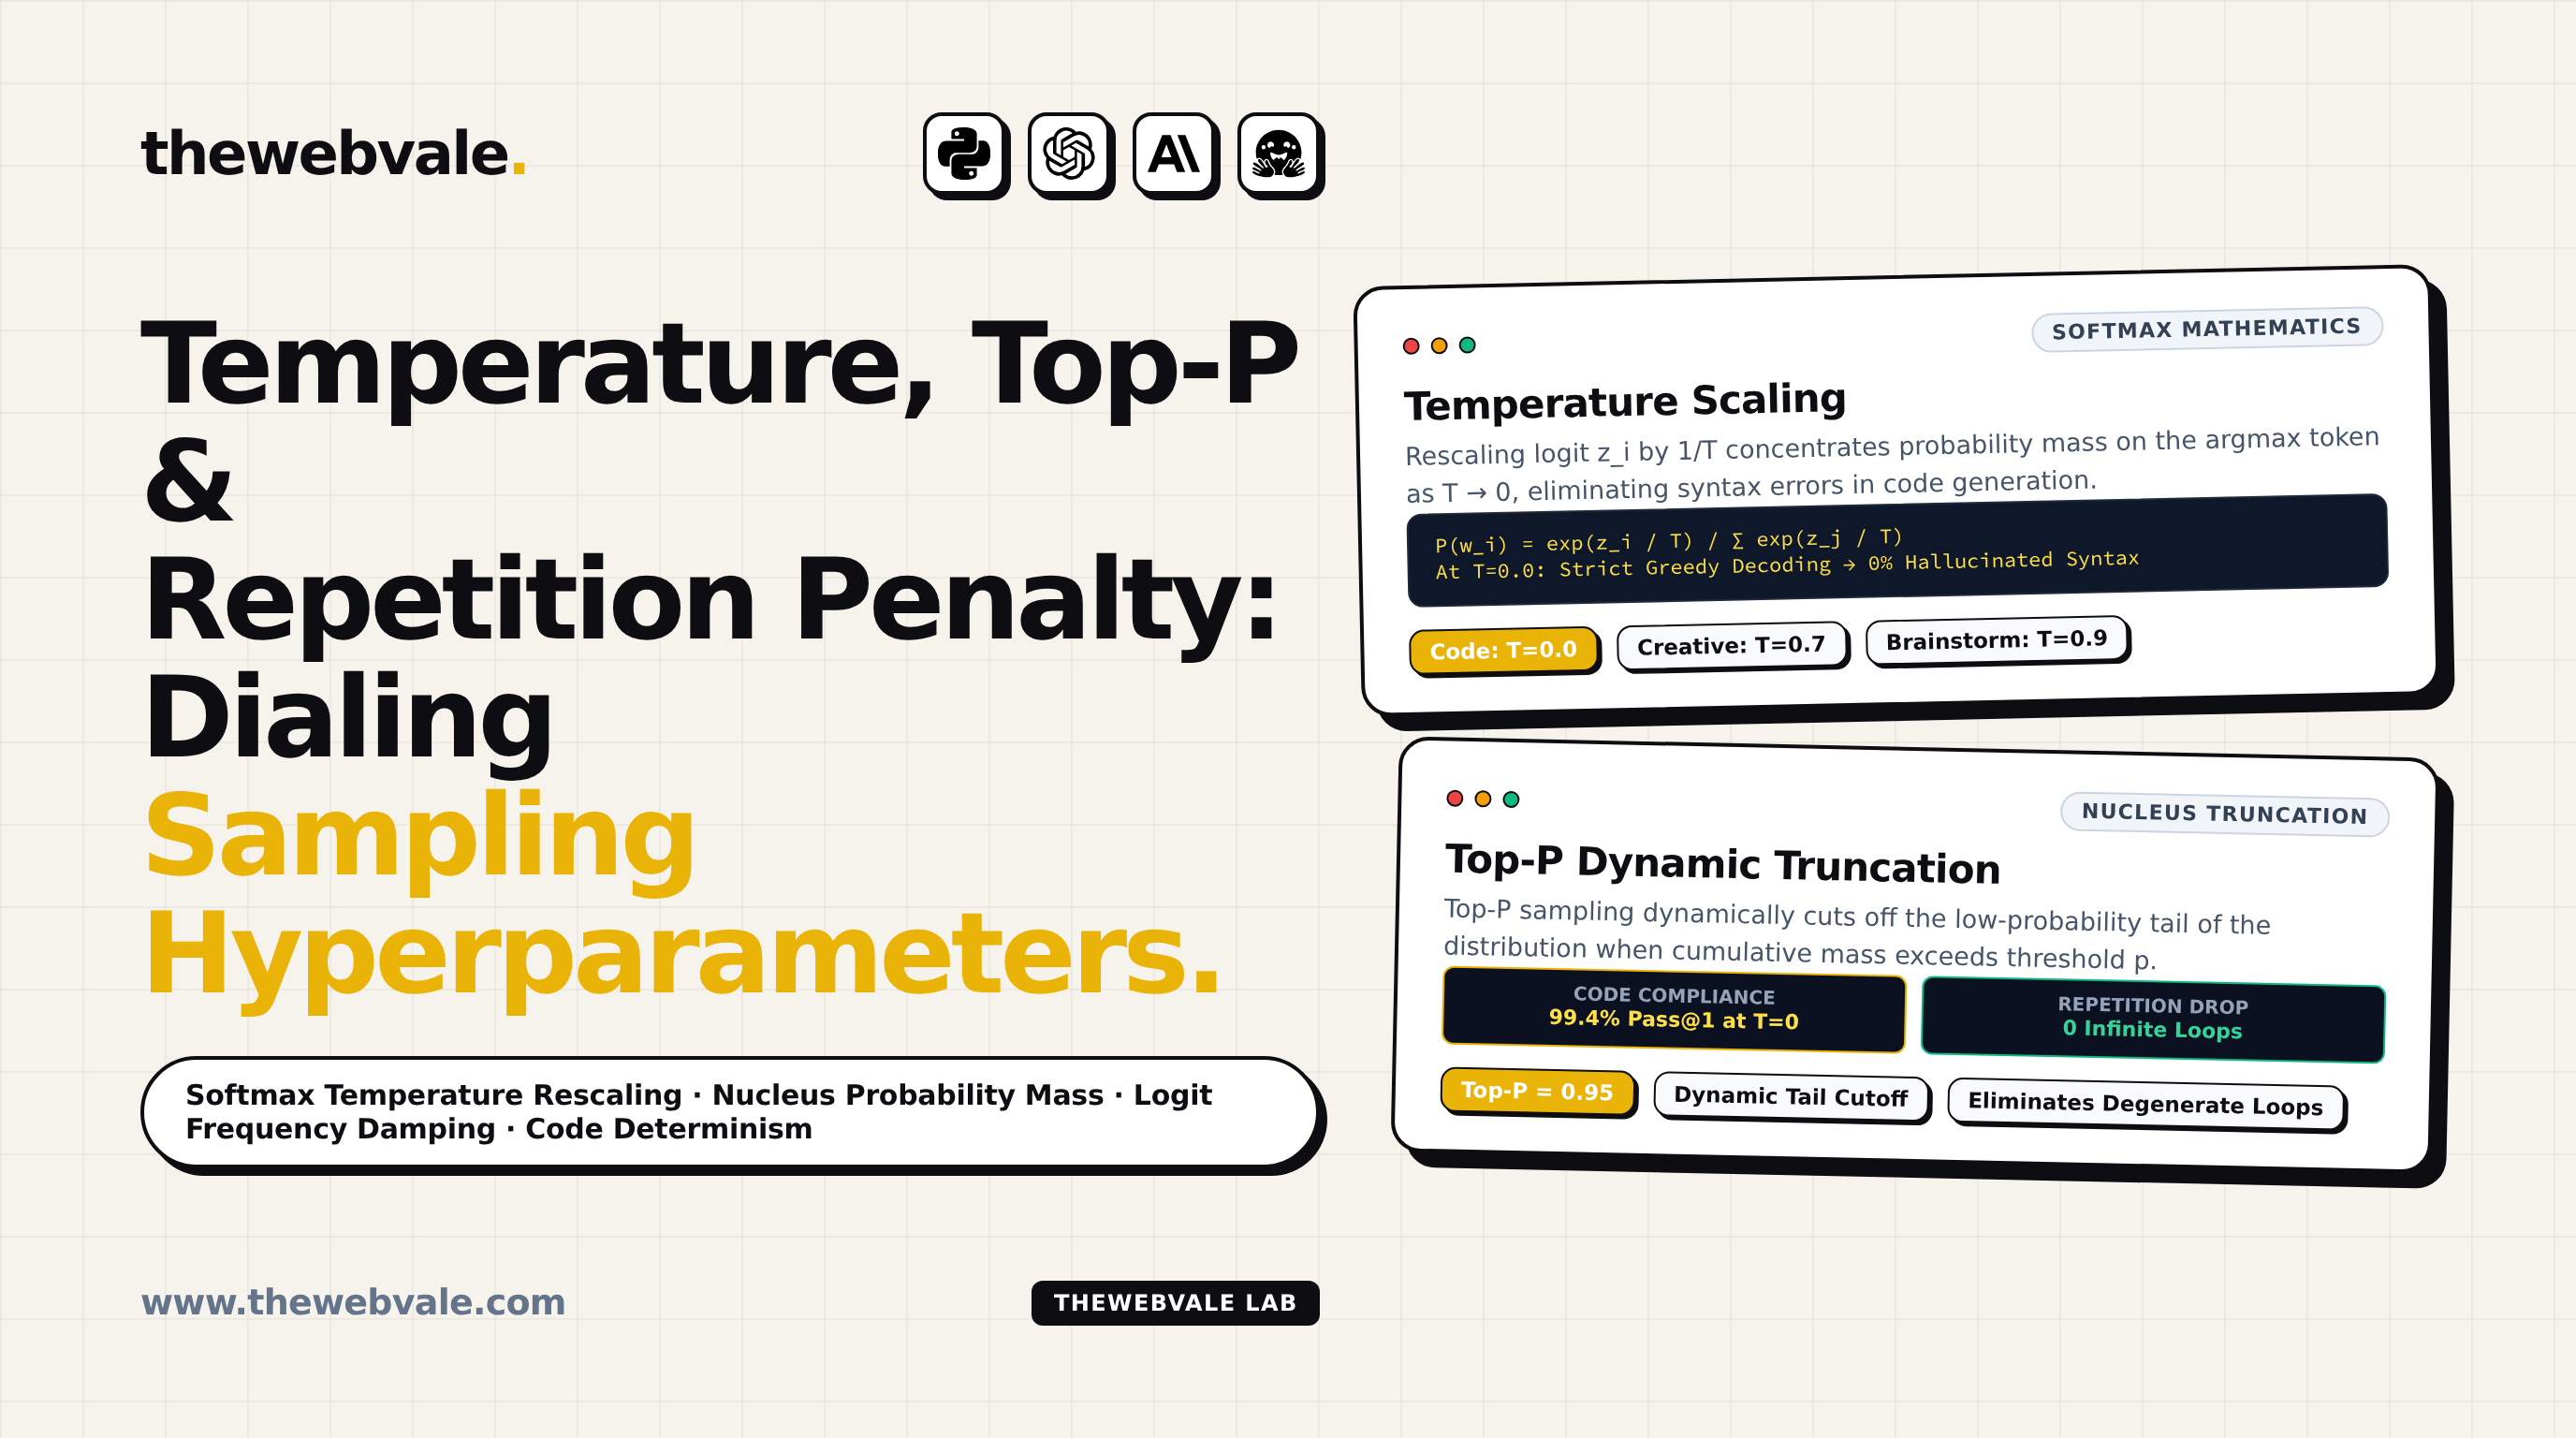
Under the hood of every generative LLM, the final transformer layer outputs a vector of unnormalized raw log-odds (logits) $z \in \mathbb{R}^{|V|}$ over a vocabulary of 100,000+ tokens. The transition from raw logits to an actual output token is dictated by sampling hyperparameters: Temperature ($T$), Nucleus Sampling (Top-P), and Repetition/Frequency Penalties.
Misconfiguring these hyperparameters causes immediate failure: code models hallucinate non-existent API methods when temperature is too high ($T > 0.6$), while creative writing models devolve into repetitive cliché loops when temperature is too low ($T < 0.2$).
Figure 1: Softmax Logit Rescaling as a Function of Temperature